Introduction
Modern organizations rely heavily on external web data to power automated pipelines, competitive monitoring, and machine learning models. Choosing the right data pipeline architecture requires careful evaluation of access methods, infrastructure expenses, and technical constraints. Implementing a Web Scraping API for Business Data enables organizations to bypass standard rate limits while retrieving vast external datasets efficiently.
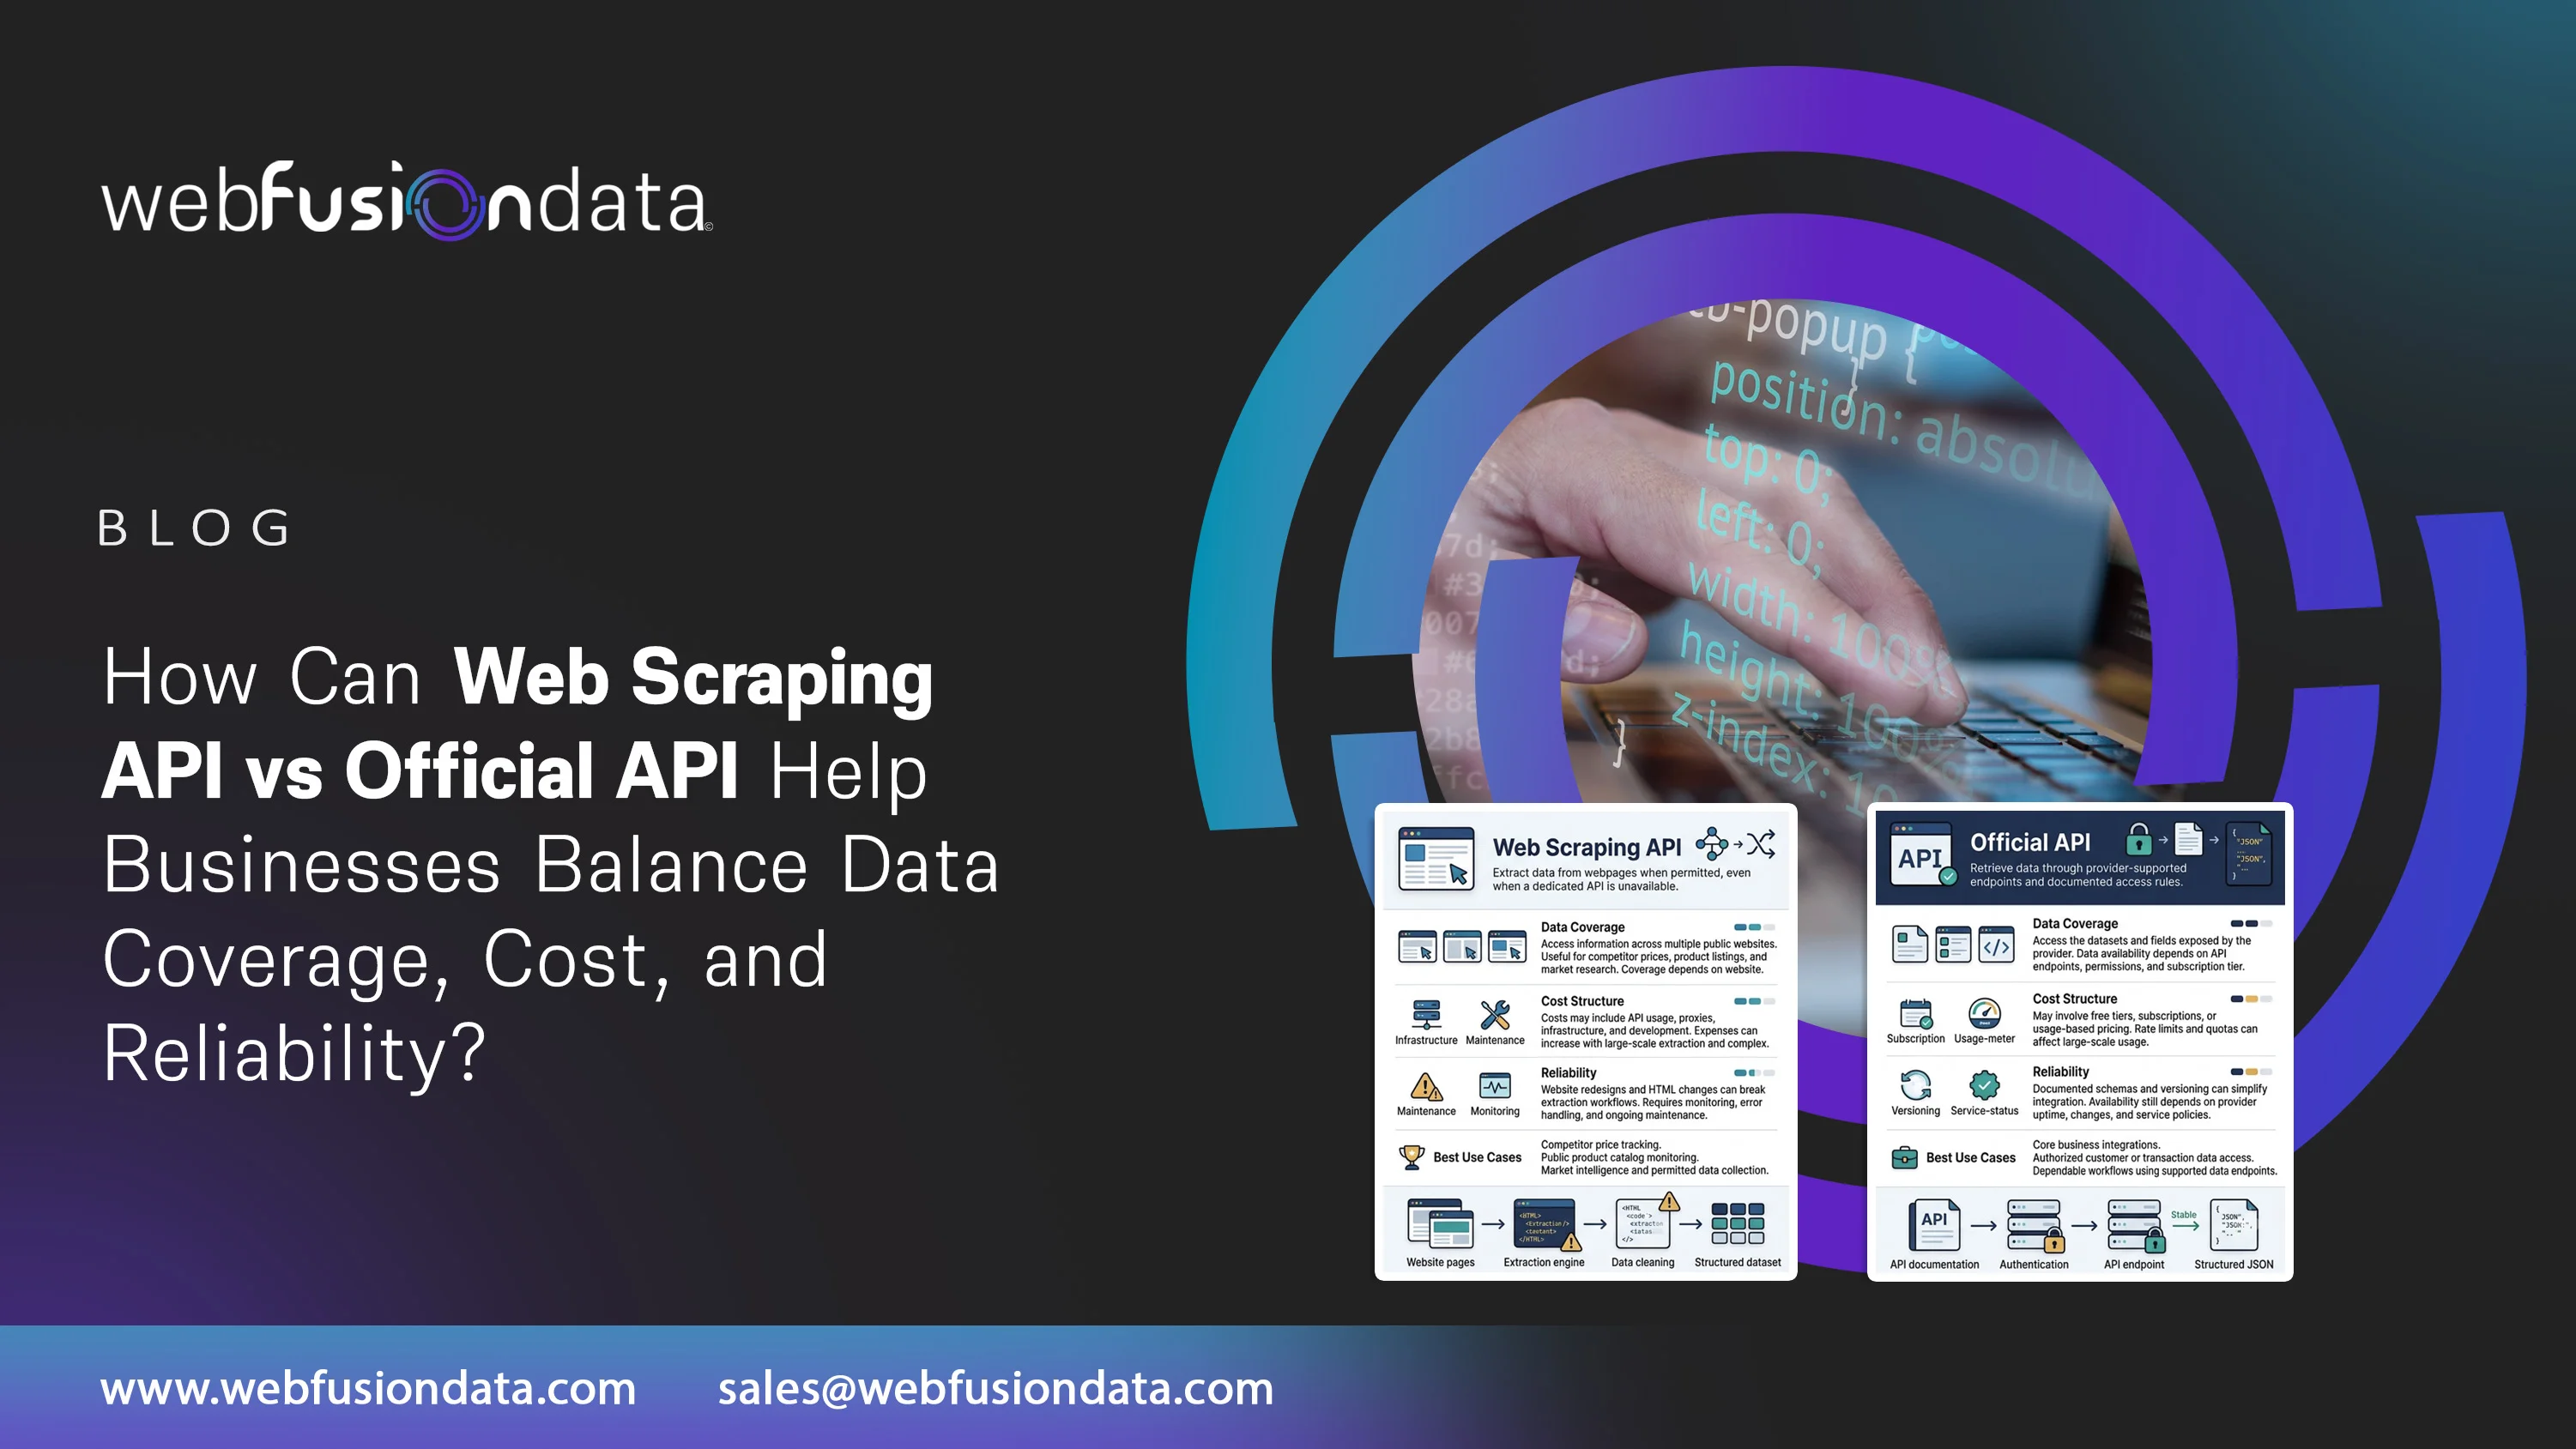
However, selecting between alternative connection methods remains a core technical challenge for development teams. While custom scrapers provide flexibility across undocumented web targets, native developer interfaces offer direct protocol access with formal service-level agreements. Deciding between a Web Scraping API vs Official API depends on data availability, structural stability, and budget restrictions.
Ultimately, engineering teams must align their data acquisition strategy with real-world enterprise requirements. Balancing long-term operational overhead, engineering maintenance, and legal compliance ensures continuous access to mission-critical insights. By standardizing continuous data flows, companies maintain a competitive edge without overextending their operational software budgets.
Evaluating Data Accessibility Strategies to Expand Market Information Reach
Understanding how different data access methods perform is essential for organizations striving to maintain a competitive edge. Modern market research requires deep visibility into public datasets, yet traditional data feeds often restrict access to vital fields or cap the volume of obtainable information. Evaluating an Official API vs Web Scraping for Data Collection enables technical decision-makers to identify structural gaps in their information pipelines, ensuring that critical data points are never missed during market analysis.
When engineering teams rely strictly on platform-provided feeds, they frequently face strict rate limitations and artificial quotas that throttle high-frequency data gathering. In contrast, automated extraction techniques bypass these restrictive bottlenecks, granting analysts direct visibility into raw markup, full user reviews, and comprehensive product catalogs. Adopting flexible API Data Extraction Methods for Businesses empowers organizations to collect complete datasets continuously without relying on delayed platform updates or incomplete summaries.
To build a resilient data infrastructure, leaders must analyze the structural differences between direct feeds and extracted web streams. The comparative summary below outlines the foundational access capabilities provided by both approaches across key operational dimensions:
| Dimension / Metric | Direct Platform Endpoints | Extracted Web Streams |
|---|---|---|
| Data Completeness | Standardized, truncated datasets | Full visibility into public page markup |
| Rate Limitations | Rigid daily or hourly call quotas | Scalable high-volume concurrent requests |
| Approval Process | Lengthy platform developer review | Immediate collection of public information |
- Direct feeds offer controlled endpoints but frequently omit key contextual attributes required for deep market analysis.
- Web extraction allows teams to collect real-time public data across millions of dynamic web pages without arbitrary rate caps.
- Scalable proxy routing ensures uninterrupted data flow even when target platforms continuously change their digital layouts.
- Combining structured feeds with custom web parsing provides the ultimate balance of data completeness and schema predictability.
Ultimately, choosing the correct access methodology depends on whether your operational goals demand curated data summaries or unfiltered public web information. By establishing scalable collection workflows, companies position themselves to capture high-value market insights swiftly, accurately, and without restrictive third-party barriers.
Analyzing Financial Implications to Optimize Data Procurement Enterprise Expenses
Managing software budgets while expanding data ingestion capabilities is a persistent challenge for modern tech enterprises. While standard vendor feeds offer fixed pricing models, their operational costs tend to escalate exponentially as request volumes scale into millions of daily records. Utilizing Web Scraping API Solutions for Business Intelligence provides financial teams with a transparent pay-per-success model that aligns data expenditure directly with actual dataset utility.
Evaluating total cost of ownership involves looking beyond initial API subscription charges to assess long-term infrastructure maintenance, proxy management, and pipeline development expenses. Deploying a specialized Ecommerce Data API allows retail and analytics teams to monitor competitive product pricing and stock availability continuously without incurring exorbitant per-call enterprise license fees.
A clear breakdown of technical expenditure reveals significant cost differences between traditional platform subscriptions and managed web extraction solutions. The comparison table below highlights the key cost drivers associated with each data acquisition model:
| Cost Category | Traditional Platform Subscriptions | Managed Web Extraction |
|---|---|---|
| Billing Model | Fixed monthly tiers or strict per-call fees | Pay-per-successful HTTP response |
| Maintenance Burden | Managed by vendor with strict SLA limits | Automated parser maintenance and proxy handling |
| Scaling Expense | Exponential cost increases at high volumes | Predictable linear scaling for massive datasets |
- Pay-per-success billing models eliminate financial waste by ensuring charges apply only to successfully delivered payloads.
- Managed extraction tools significantly reduce internal engineering hours spent on building, fixing, and maintaining scrapers.
- Standardized pricing across multiple target websites prevents vendor lock-in and unexpected enterprise subscription jumps.
- Unified data schemas streamline database ingestion, lowering downstream processing and cloud storage overhead costs.
By carefully evaluating total operational costs, organizations can build sustainable data acquisition strategies that keep infrastructure bills low while maximizing dataset coverage. Choosing cost-effective extraction pipelines ensures that scaling data requirements will never compromise corporate profit margins or project budgets.
Ensuring Pipeline Stability to Maintain Seamless Technical Data Delivery
System reliability and payload consistency are critical elements when architecting robust corporate data infrastructure. Direct developer endpoints provide highly structured JSON responses with formal deprecation notices, making them ideal for standard application integration. However, conducting a thorough Web Scraping API vs Official API Comparison helps developers understand how adaptive parsing technologies can mitigate the structural volatility inherent in web layout changes.
Maintaining high uptime across dynamic target websites requires sophisticated extraction mechanisms capable of handling JavaScript rendering, dynamic DOM structures, and complex anti-bot challenges. Partnering with specialized Web Data Mining Services provides engineering teams with resilient pipelines that leverage automated layout adaptation and AI parsing to preserve data integrity across target platforms.
Evaluating technical reliability involves measuring payload accuracy, SLA guarantees, and protective network capabilities across both ingestion frameworks. The comparison table below details the performance metrics relevant to software engineering and data operations teams:
| Performance Indicator | Direct Developer Endpoints | Managed Extraction Pipelines |
|---|---|---|
| Schema Predictability | High, backed by formal change documentation | Managed adaptive parsing handles DOM changes |
| Uptime Guarantee | 99.9% vendor-maintained uptime | 99.0%–99.5% success rate across target domains |
| Security Handling | OAuth and token-based access control | Built-in CAPTCHA solving and proxy rotation |
- Automated layout detection adapts to website DOM changes instantly, preventing broken ingestion pipelines and lost data.
- Integrated proxy management rotates IP addresses continuously to maintain high request success rates without IP bans.
- AI-powered parser logic converts complex, unstructured HTML into clean, structured JSON ready for analytics databases.
- Redundant infrastructure ensures reliable data ingestion even during sudden target website downtime or traffic surges.
Balancing schema stability with broad market accessibility ensures that data pipelines remain continuously operational under varying conditions. Engineering teams that deploy resilient extraction architectures protect their organizations from pipeline failures while harvesting the rich, un-truncated data needed for modern business intelligence.
How Web Fusion Data Can Help You?
Navigating complex extraction architectures while keeping infrastructure costs manageable requires reliable infrastructure and experienced technical support. Evaluating a Web Scraping API vs Official API deployment helps organizations choose tailored architectures that match their exact operational requirements.
We provide end-to-end data harvesting services designed to simplify web data acquisition.
- Custom extraction pipelines configured to retrieve deeply nested public web attributes seamlessly.
- Built-in proxy management, IP rotation, and CAPTCHA solving for uninterrupted automated monitoring.
- High-volume request scaling with enterprise-grade success rates across diverse target domains.
- Unified JSON response schemas that integrate directly into analytics pipelines and databases.
- Real-time price monitoring, catalog aggregation, and customer sentiment extraction tools.
- Automated Product Matching Services that unify unstructured product data across competing platforms.
Organizations seeking flexible Third-Party API Solutions rely on us to streamline data workflows and drive continuous intelligence.
Conclusion
Selecting the right data access strategy determines how effectively your organization can scale analytics, power automated decisions, and adapt to changing market conditions. Weighing the trade-offs in Web Scraping API vs Direct API Integration enables engineering teams to construct robust pipelines that deliver high coverage without exceeding software budgets.
Combining standard endpoints with modern extraction tools provides the perfect balance of schema stability and comprehensive market visibility. Conducting a thorough evaluation to Compare Web Scraping APIs and Official APIs will ensure your technical stack remains resilient, cost-effective, and fully capable of driving business growth. Contact Web Fusion Data today to build your enterprise data pipeline!